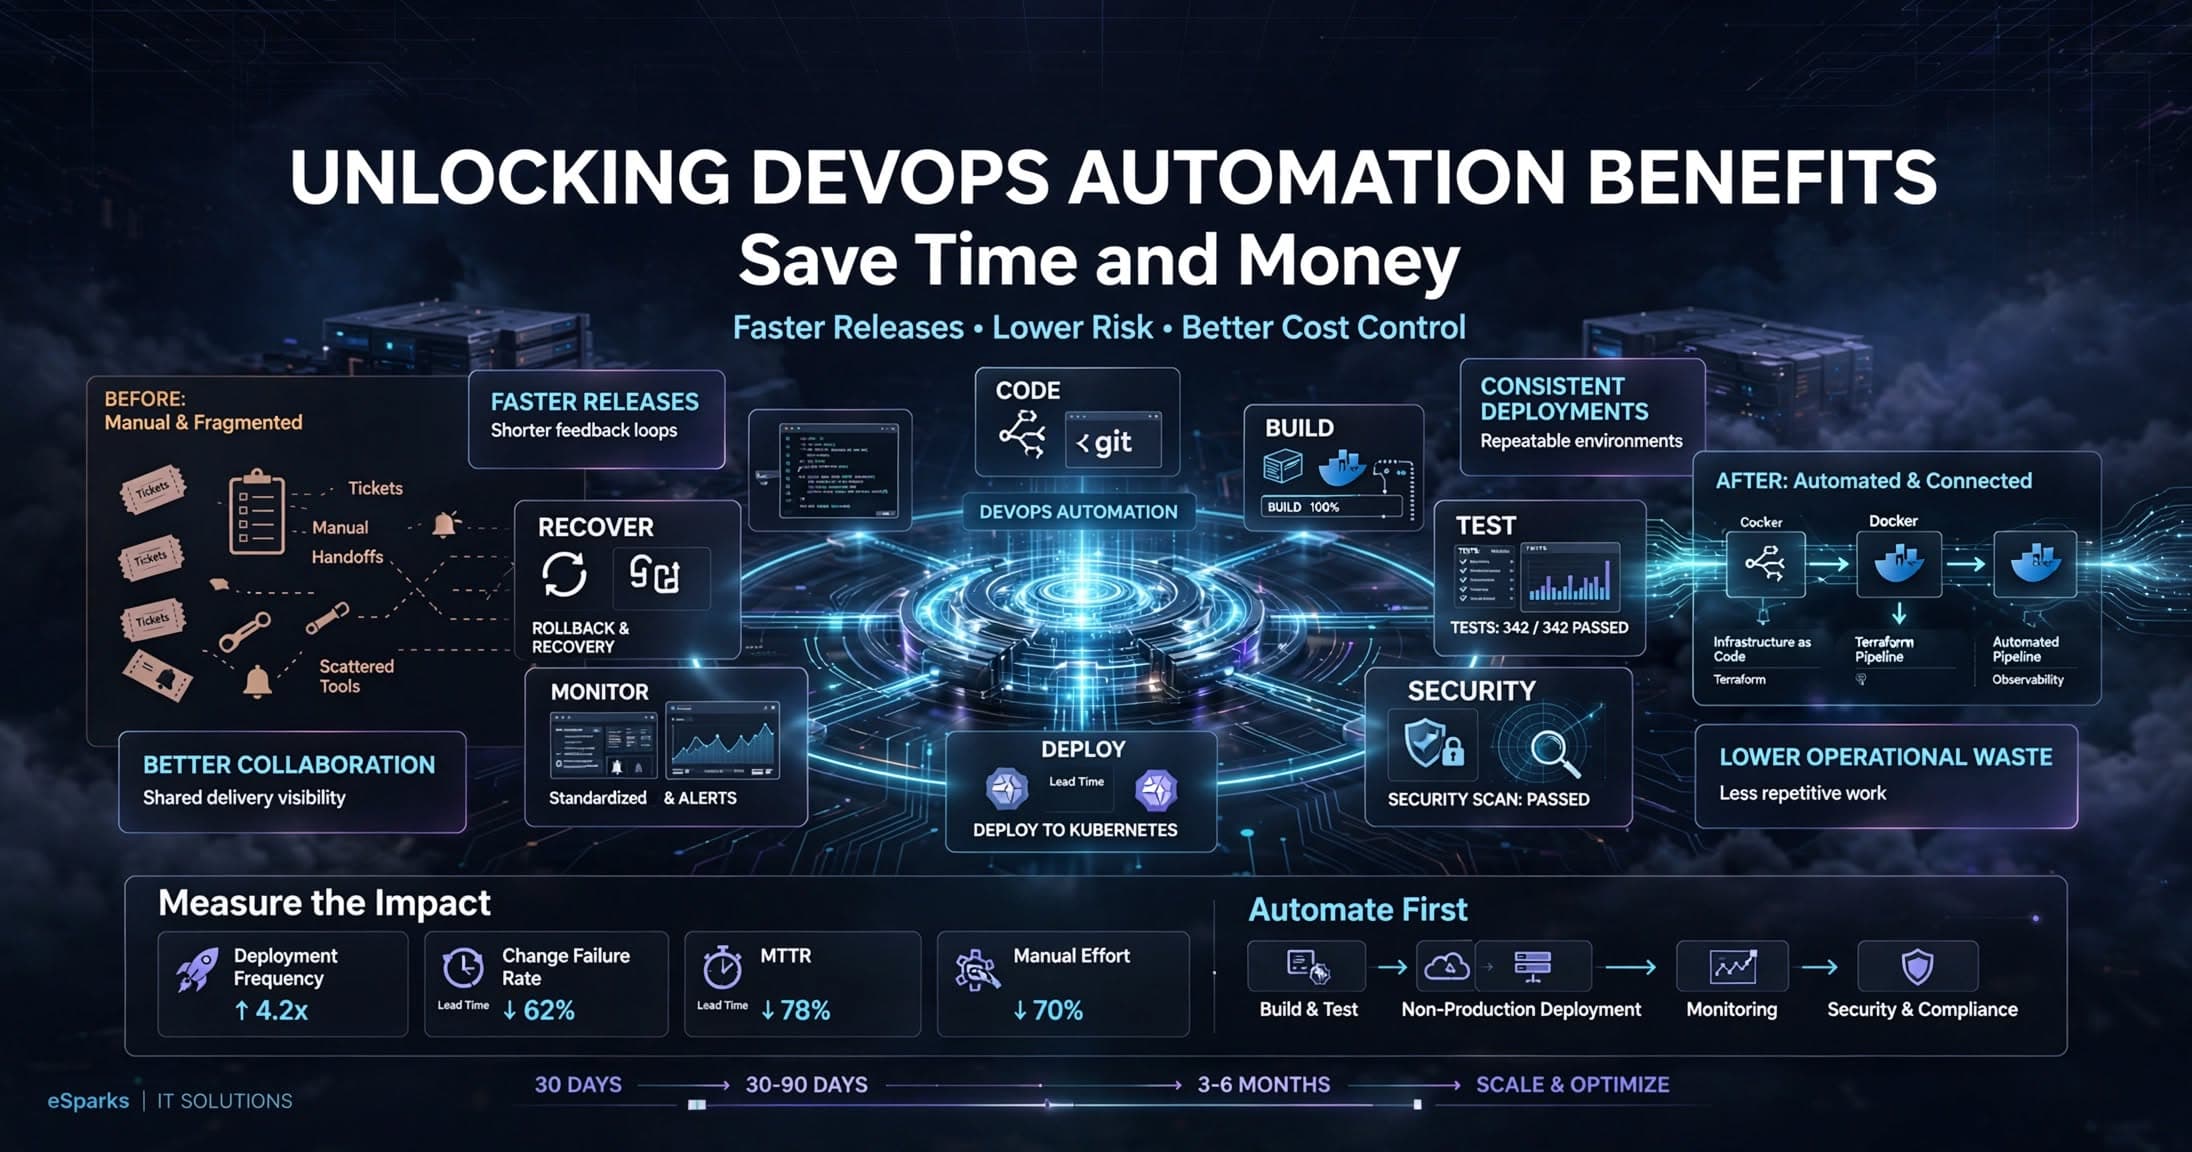
Automate the build and test step first, then deployments to non-production, then production deploys with rollback, then infrastructure, then backups and output-based monitoring. Pick the order by how often a task happens and how badly it fails when done by hand. Then plan for automation failing too: jobs that stop without anyone noticing, limits that never fire, and config that drifts away from what is running.
Key takeaways
- Rank tasks by frequency multiplied by the cost of a manual mistake, not by what is most interesting to automate.
- Every automated job needs a check on its output, not just on whether the process is up. "The service returns 200" and "the work got done" are different questions.
- Config that lives only on a server will be overwritten by the next deploy. If it is not in the repo, it does not exist.
- Schedulers drop and repeat runs. Any scheduled job that changes state needs an idempotency guard.
- Measure with DORA's four key metrics: deployment frequency, lead time for changes, change failure rate and time to restore service.
The automation order, ranked
The rule we use: automate what happens often, takes real time, and fails in predictable ways. A rare, highly variable task is often better written down as a runbook than scripted. The table is a starting order for a typical product team with a handful of services. Your frequencies will differ, but the reasoning carries over.
| Priority | Task | How often | Cost of doing it by hand | What can go wrong once automated |
|---|---|---|---|---|
| 1 | Build, lint and unit tests on every push | Many times a day | Skipped tests, "works on my machine" merges | Flaky tests teach people to re-run until green; slow pipelines get bypassed |
| 2 | Deploy to staging/preview | Daily | Hours of waiting; staging drifts from main | Staging becomes the place broken builds pile up unnoticed |
| 3 | Production deploy with health check and rollback | Weekly to daily | Release-day checklists, missed steps, weekend releases | Deploy overwrites server-side hotfixes; health check passes while the app is broken |
| 4 | Infrastructure as code (servers, networks, containers) | Monthly, plus every incident | Hand-built environments nobody can rebuild | Hard-coded addresses, missing resource limits copied everywhere |
| 5 | Backups and restore tests | Nightly | Backups forgotten or stored on the same host | Backups "succeed" but are empty, unreadable or deletable by an attacker |
| 6 | Scheduled jobs (reports, content, syncs) | Daily or hourly | Someone has to remember | Runs delayed, dropped or duplicated |
| 7 | Monitoring and alerting | Continuous | Users find outages before you do | Alerts on uptime only; alert fatigue makes real alerts invisible |
| 8 | Security checks (dependency scans, secret detection) | Every push | Rarely done at all | Noisy findings that everyone learns to ignore |
Two notes on the order. First, steps 1 to 3 give you a pipeline you trust, and nothing after them is safe without it: automating infrastructure changes through a pipeline nobody trusts just spreads the mess faster. Second, backups sit above monitoring on purpose. A missing backup is the one failure you cannot fix after the fact.
Where automation fails: four things we ran into
Most articles about DevOps automation list the benefits. The more useful knowledge is how automated systems fail, because they fail quietly. A manual process that breaks gets noticed by the person doing it. An automated one that breaks keeps reporting success. These are from our own production systems.
1. The health check that only checked "is it up"
What happened. On our own site, a monitor kept returning 200 while the background jobs it existed to watch had silently stopped. The web process was healthy. The work it was supposed to do had not happened for days.
What we changed. We replaced liveness checks with checks on the job's output: "was a post published today", "did last night's backup land". We also alert only on a change of state (pass to fail, fail to pass) instead of on every failed check, so an alert means something and does not get muted.
The general rule. For every automated job, write down the observable result it should produce and check for that result. Uptime is necessary but tells you almost nothing.
2. The scheduler that skipped days
What happened. We ran a daily job on a hosted CI provider's built-in scheduler. In practice it delayed runs by up to 11 hours and sometimes dropped a whole day's run.
What we changed. We moved the trigger to a cron on our own server that calls the CI provider's API to start the workflow. Because we now had two possible triggers during the changeover, and because retries happen, we added an idempotency guard: before publishing, the job checks whether today's output already exists and exits cleanly if it does.
The general rule. Treat any scheduler as "at least once, roughly on time". Design scheduled jobs so that running them twice is harmless and missing one gets caught by an output check (see lesson 1).
3. Memory caps that never fired, and a hotfix the deploy erased
What happened. The process manager had a memory-restart limit configured, but its monitoring was broken, so the app ran at about three times the cap with nobody noticing. When the monitoring was fixed, the cap turned out to be far too low and would have put the site into a restart loop. Along the way, a fix applied directly on the server was overwritten by the next deploy, because the deploy shipped the config from the repo.
What we changed. We set limits from measured memory use under real crawler load, not from a guess. We moved all process config into the repo so the deploy is the only way it changes. And we tested that the limit actually triggers a restart, instead of assuming it does.
The general rule. A limit you have never seen fire is untested code. Config that only exists on the server is a bug waiting for the next deploy.
4. A hard-coded address that went stale
What happened. In one of our deployments, a database connection pooler was configured with the database container's internal IP address. After a container restart the database came back on a different address, the pooler kept pointing at the old one, and the CMS returned 500 errors.
What we changed. Services now find each other by name on a shared Docker network. Nothing in config refers to a container by IP.
The general rule. Automated restarts and rebuilds are great until something holds a reference to the old state. Search your infrastructure code for literal IPs and replace them with names or service discovery.
A pre-flight checklist for any new automation
Before a new pipeline step, scheduled job or infrastructure change counts as done, it should pass this list:
- Output check exists. There is a monitor that confirms the job's result, not just that the process ran, and it alerts within one expected run interval (a daily job alerts within 24 to 26 hours).
- Safe to run twice. Running it again does not double-publish, double-charge or double-send.
- Config is in the repo. No step depends on a file edited by hand on a server.
- Limits are measured. Memory and CPU limits come from observed peak use plus headroom (for example, 1.5x observed peak), and you have seen the limit trigger at least once in a test.
- No literal addresses. Services are referenced by name.
- Rollback is one action. Undoing a bad deploy is a single command or button, and someone has done it recently.
- Backups are off-host and restorable. Backups go to separate storage, using a credential that can write but not delete, and a restore has been tested in the last quarter.
- Someone owns it. If the person who wrote it leaves, another person can read and fix it.
Item 7 deserves one more line. We write nightly database dumps to off-host object storage with date-stamped keys and a write-only credential, so a compromised server can neither read nor delete the copies meant to save it.
Container limits: the cheapest fix on this list
If you run long-lived containers, give each one a memory limit. On one of our hosts, several containers had none, and one grew past 1.2 GB over two weeks. Without a limit, slow growth like that shows up as the whole host getting sluggish, and every service suffers at once. With a limit, the same leak becomes a single container restart that your monitoring can see and count. It takes one line of config per service and turns an invisible, host-wide problem into a visible, local one.
Measuring it: DORA's four key metrics
DORA (DevOps Research and Assessment, now part of Google Cloud) has spent years studying what separates high-performing delivery teams. Its four key metrics are the standard way to tell whether automation is helping:
| Metric | What it measures | Type |
|---|---|---|
| Deployment frequency | How often you deploy to production | Throughput |
| Lead time for changes | Time from a commit to that commit running in production | Throughput |
| Change failure rate | Share of deployments that cause a failure needing a fix, rollback or hotfix | Stability |
| Time to restore service | How long it takes to recover from a failure in production | Stability |
Recent DORA reports call the fourth metric "failed deployment recovery time", but it measures the same thing. The point of having two throughput and two stability metrics is that you cannot game one without the other showing it. Shipping more often while change failure rate climbs is not progress.
Practical advice for small teams:
- Take a baseline before you automate. Even a rough count from your git history and incident notes for the last 90 days is enough.
- Pull the numbers from your tools, not from memory. Deploy frequency and lead time come from CI and git. Failure rate and restore time come from your incident log, so keep one, even if it is a shared document.
- Add one local metric: manual steps per release. It is not a DORA metric, but it is the number automation is supposed to drive toward zero.
- Review monthly, not daily. These metrics are noisy week to week for a small team.
If you want help setting up the pipeline, infrastructure and monitoring described here, that is the work our DevOps team does, usually alongside cloud infrastructure and ongoing support and maintenance.
Frequently Asked Questions
What should be automated first in DevOps?
Start with build and test on every push, because it runs most often and every later step depends on it. Next, automate deploys to staging, then production deploys with a health check and one-step rollback. Infrastructure provisioning, backups and monitoring come after you have a pipeline you trust.
What are the risks of DevOps automation?
The main risk is silent failure: an automated job stops or produces bad output while still reporting success. Others are config drift when servers are hand-edited, duplicate runs from schedulers that retry, and resource limits that are set but never tested. Output-based monitoring and idempotent jobs address most of these.
What are the four DORA metrics?
Deployment frequency, lead time for changes, change failure rate and time to restore service (called failed deployment recovery time in recent reports). The first two measure throughput and the last two measure stability. Track all four together so speed gains do not hide reliability losses.
How do you monitor automated jobs like backups or cron tasks?
Check the output, not the process. For a backup, confirm that a new file with today's date exists and is a plausible size. For a scheduled job, confirm that its result appeared within the expected window, and alert on changes of state so alerts stay meaningful.
How long does it take to automate a deployment pipeline?
For a single application with an existing test suite, a basic build, test and deploy pipeline with rollback is typically a few days to two weeks of work for one engineer. Infrastructure as code, backups and monitoring across several services add several more weeks. The estimate grows mostly with the number of environments and how much hand-built infrastructure has to be reverse-engineered first.
Work with Esparks IT Solutions
Planning a project around this? We work with businesses in the United States, Canada and the UAE, as well as the UK and Australia. Explore our Cloud Computing services and portfolio, estimate your project cost, or book a free call.